 Bad Boy Labs
At Mohan's Catering, a customer called before the same-day ordering cutoff. The AI receptionist told them they were too late.
The business had a clear rule. The AI still gave the wrong answer.
That is a useful place to start when someone says they want AI to use their company information. You need to work out what it should look up, what it should calculate and what it should check with another system.
RAG handles the lookup part. The examples below come from our work on Mohan's Catering and CargoMode. They show where retrieval helps and where another approach belongs.
What RAG actually does
RAG stands for retrieval-augmented generation. Think of it as giving the AI a reference desk.
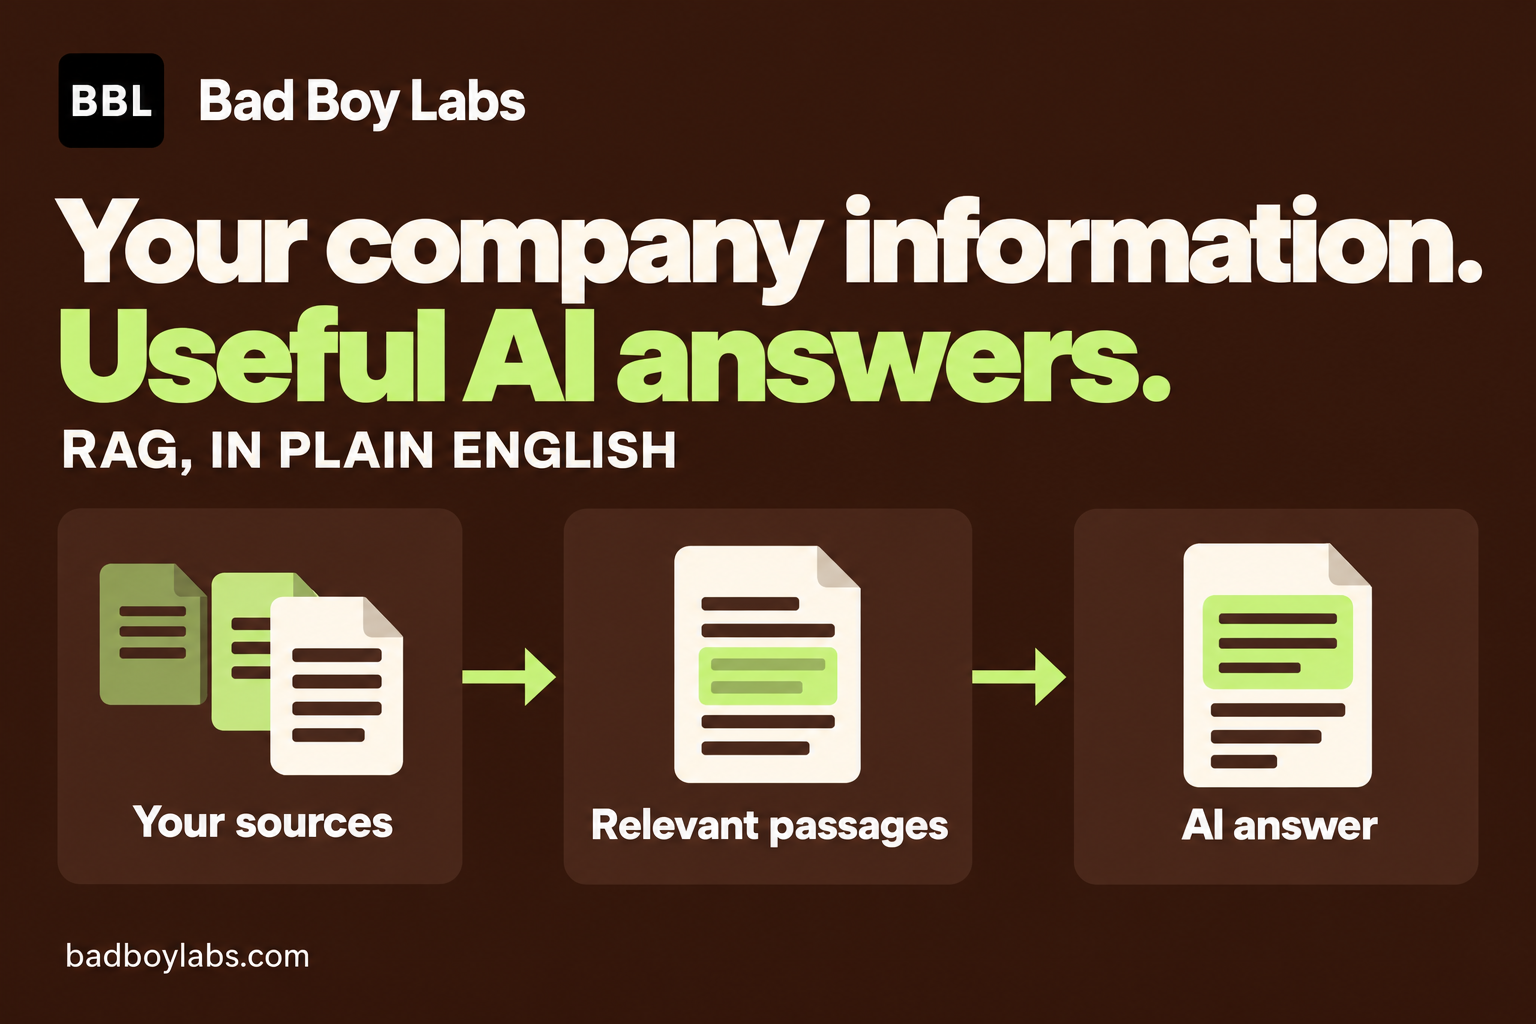
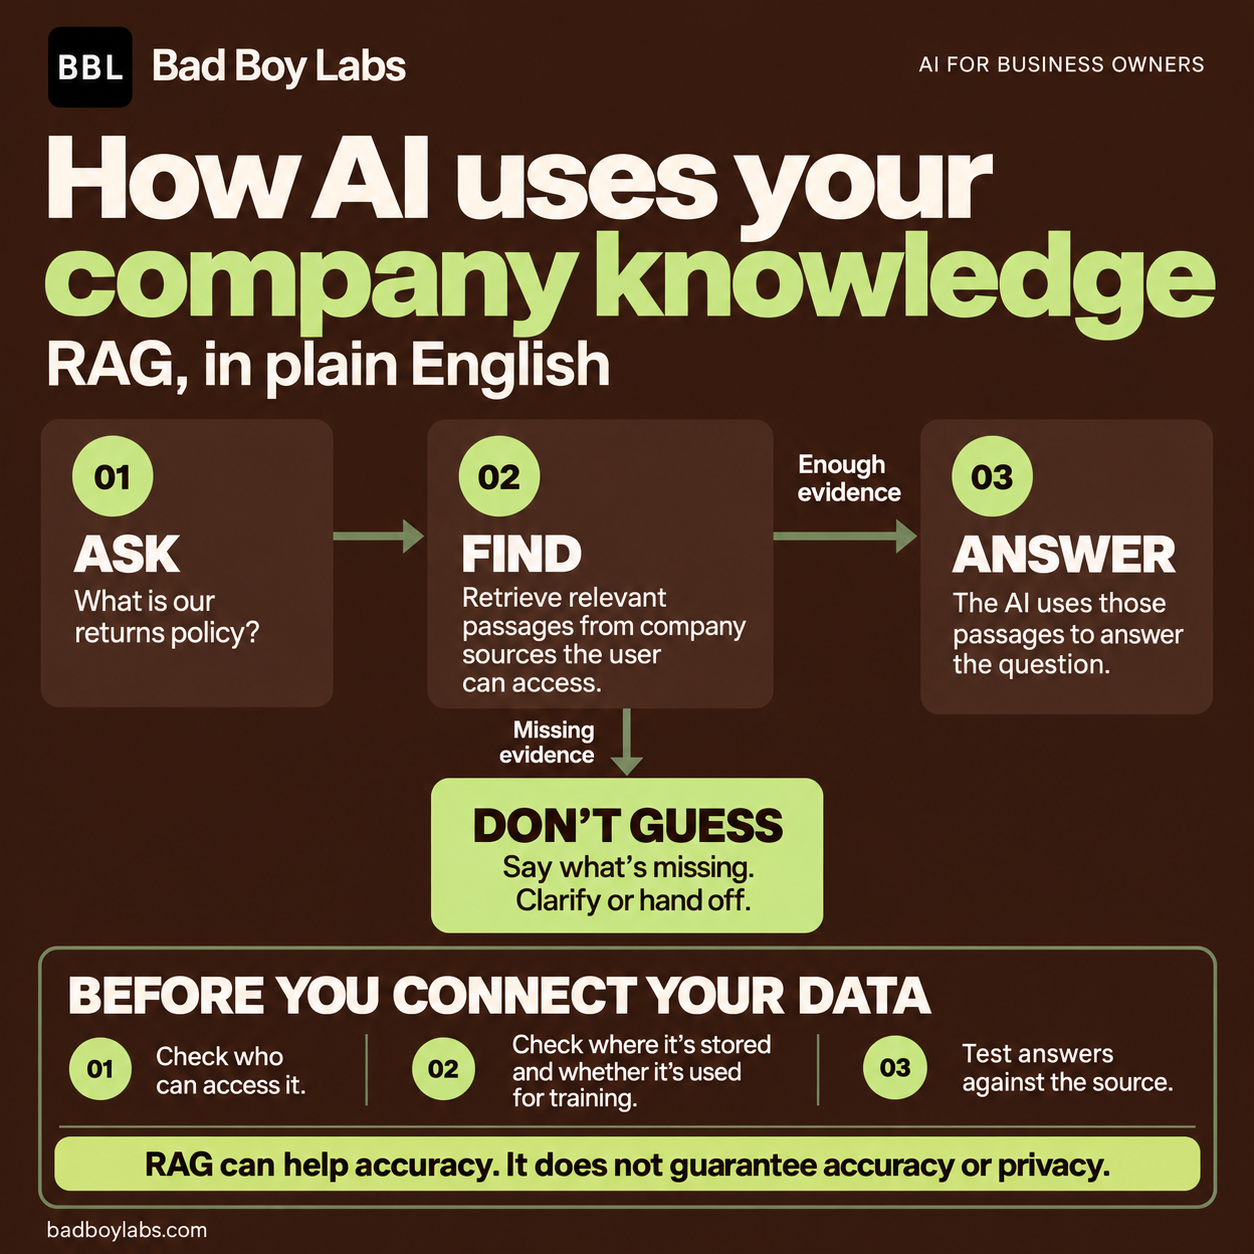
When someone asks about a service, a package or its pricing, the application searches the company information that person is allowed to access. It passes the relevant passages to the model along with the question. The model uses that material to write an answer.
That is the basic flow: find the information, put it in context, then answer. Microsoft's explanation of RAG describes the same process.
You are supplying information for that answer. You do not need to retrain the model each time a document changes.
Mohan's Catering: getting the cutoff right
In October, a caller asked to place a same-day order at 11:20 am. The receptionist said ordering had closed because it was past 2 pm.
The model had a clock value and a written cutoff rule. It was being left to interpret the timing itself.
We changed the prompt template to use London time and calculate whether same-day ordering was open or closed. The model received that decision and handled the conversation around it.
Retrieval could find the written cutoff rule. It would not, by itself, solve the mistake we found. The fix was a calculation in code. That distinction matters when choosing what to build.
You still need to check both the calculation and the customer's answer. Code can consistently apply the wrong timezone. A model can still explain a correct result badly.
CargoMode: using previous deals to prepare a quote
Pricing is another place where company information matters. In CargoMode, we built a workflow that reads a request for a quote, looks for comparable previous deals and uses the available costs to prepare a draft for review.
The matching code compares details such as the product, destination and quantity. It keeps the reason for a match and the source of the costs visible. Where the required costs are missing, the draft says the quote is being prepared instead of presenting a price.
This is structured retrieval and calculation. It does not need a language model to invent the number. A previous deal also needs reviewing before its price is reused for a new request.
For a founder, the useful distinction is practical: RAG can help explain relevant documents. Database queries can retrieve a particular record. Code can calculate a price. One workflow may need all three.
When the answer is missing
Sometimes the system finds nothing useful. Sometimes it finds two policies that disagree.
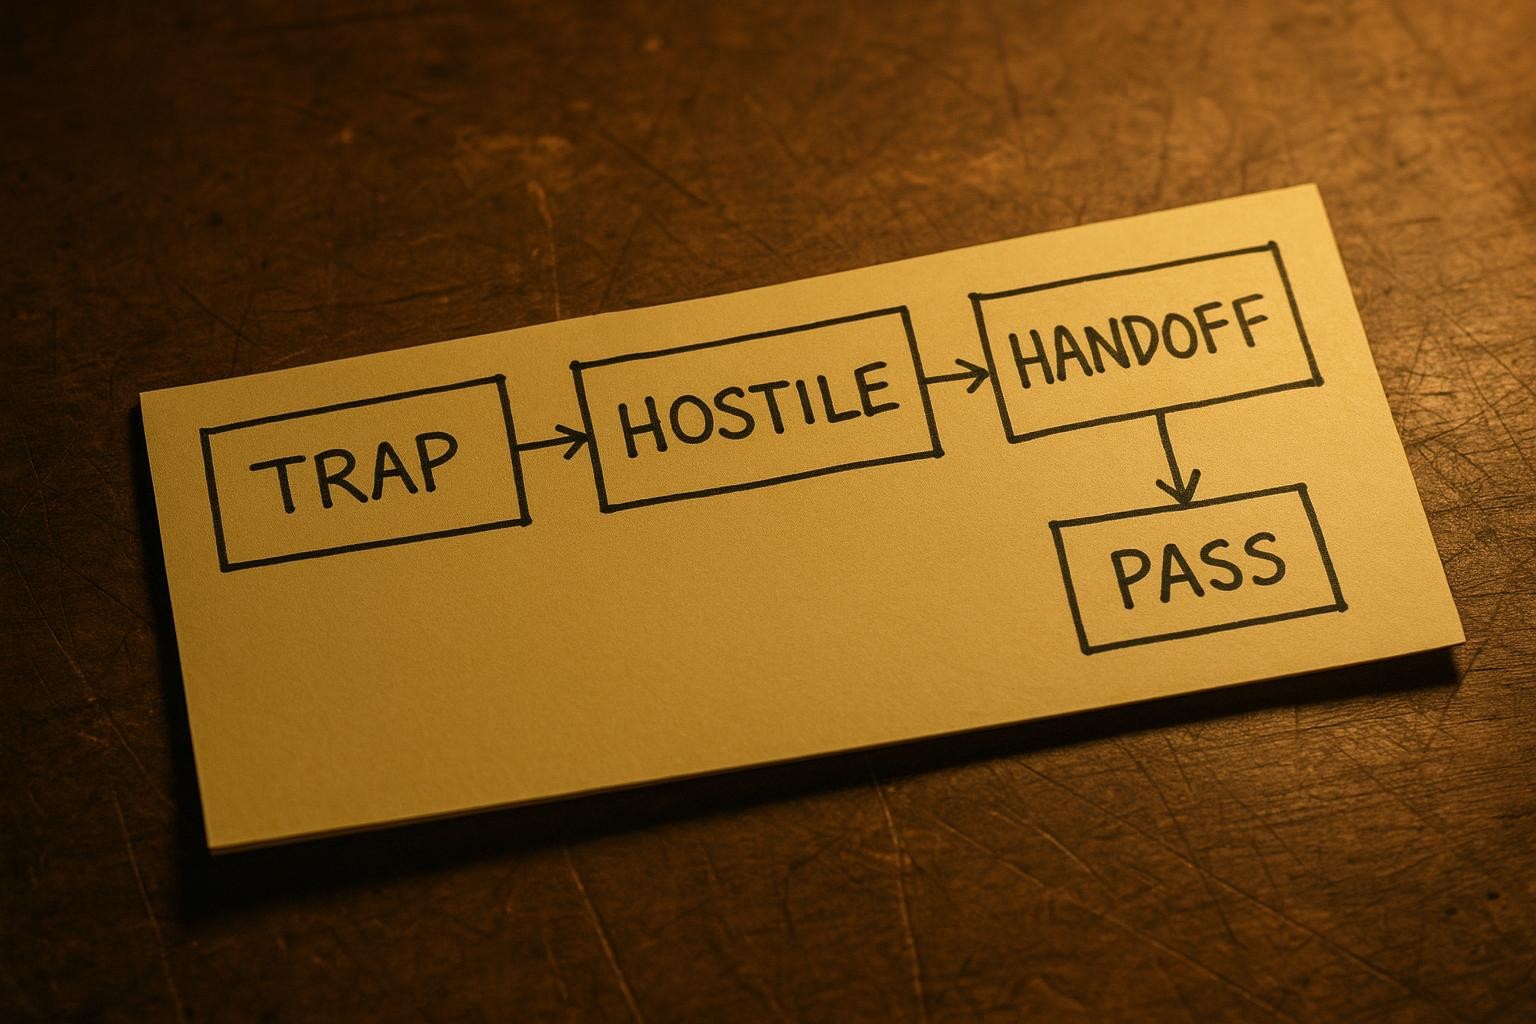
That needs a deliberate response: say what is missing, ask a clarifying question or pass the request to a person. A confident guess is a poor fallback for a customer asking about their money or an employee asking about a company rule.
Ask for a source link with the answer. Then check that the source actually supports what was said. A citation is useful evidence to inspect, not a guarantee that the answer is correct.
Give each source an owner and remove retired versions from the searchable collection. Check that updates reach the search system. Editing a price list does not prove that every connected tool has refreshed its copy.
A retrieved document also cannot confirm that an order was placed or a booking succeeded. That answer must come from the system doing the work.
Check privacy before connecting company data
RAG is an information-retrieval method. It is not a privacy setting.
Before you connect internal documents, get clear answers to four questions:
- Where does the information go? Include the document store, search service, model provider and any connected tools.
- Who can access it? Someone who cannot open a confidential document should not gain its contents through an AI answer.
- How long is it kept? Check uploaded files, conversation history, logs and backups.
- Can it be used for training? Check the actual product, plan, settings and any feedback-sharing options.
There is a difference between a provider processing your request, keeping a copy and using it to train a model.
For example, OpenAI's business policy and Anthropic's commercial policy exclude training by default, with stated opt-in or feedback exceptions. That does not mean nothing is stored. OpenAI's API data controls describe retention separately.
These are the providers' published policies, not an independent audit. Check the terms that apply to your account before sharing sensitive information.
Local models are an option, with responsibilities
A model running on equipment you control can keep the model's processing local. Ollama, for example, documents local-only operation separately from its cloud features.
But look at the whole setup. A local model connected to a hosted search service or external tools can still send information elsewhere. You also take responsibility for access controls, updates, storage, backups and the quality of the answers.
There are three sensible starting points:
- A searchable document library. If people mainly need to find and read the original policy, ordinary search may be enough.
- A hosted AI service with suitable business controls. Worth considering when its access, retention and data-use terms fit your requirements.
- A local or privately hosted setup. Worth considering when tighter control justifies the extra work to run and maintain it.
I would choose the smallest setup that meets the need. Decide what information it must use and what must stay private before choosing a model.
Start with one useful job
Pick one recurring job. That might be helping someone understand your packages, finding the information behind a quote or checking an ordering rule. Write down which parts need documents, records or calculations before choosing the technology.
Write down the expected answers before testing. Include an ordinary question, a missing answer, an outdated document, conflicting information and a request for something the person should not be allowed to see.
Review the answers and their sources with someone who knows the material. Keep those examples as repeatable checks when the documents or system change.
Then look at the work itself. Are people finding what they need? Are they correcting the AI's answers? Does the handoff work when it cannot help? That tells you more than a polished demo.
If you want help choosing a first use case, see how we approach AI customer service. Bring one recurring question and the documents your team currently uses to answer it.
Provider documentation checked on 1 November 2026. Policies and product settings can change.